CopyShield: A Cross-Level Benchmark of Copyright Defenses in LLMs
A cross-level benchmark for copyright compliance and defense evaluation in large language models.
Aug 24, 2026
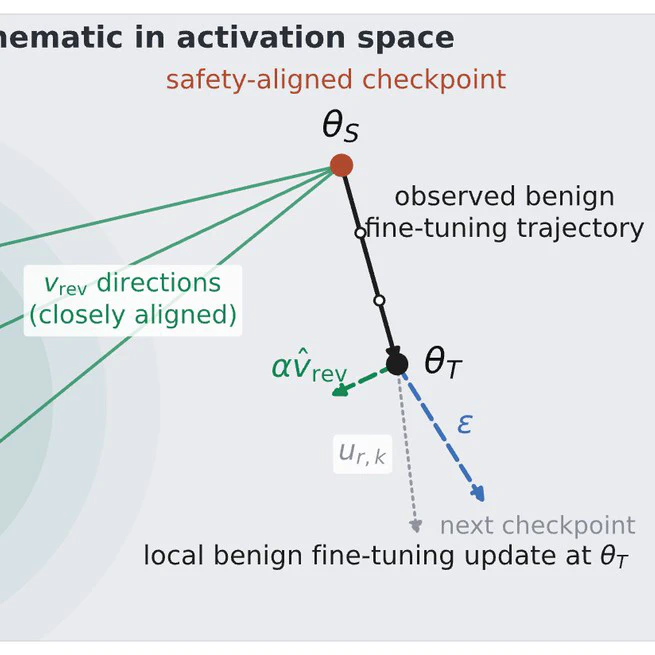
A Gravitational Interpretation of Safety Reversion under Fine-Tuning
Benign post-training pulls safety-aligned LLMs back along a reversion direction toward an earlier, more permissive state; opposing that direction reduces harmfulness across Llama, Qwen, and Gemma.
Jun 26, 2026

When the Chain of Thought Knows Better: Failure Modes in Multi-Turn Reasoning Models
A trace-level diagnostic for safety failures that terminal refusal scores can miss in multi-turn reasoning models.
Jun 9, 2026

SPQR: A Multi-Dimensional Benchmark for Safety Alignment under Benign Model Adaptation
A benchmark for testing whether text-to-image safety alignment still holds after benign fine-tuning and deployment-time adaptation.
Jun 1, 2026

Not All Attackers Are Malicious: When Safety Degrades Without Harmful Intent
A talk on how safety can silently degrade when models are adapted after deployment, even without malicious intent.
Feb 9, 2026

Safe-CLIP: Removing NSFW Concepts from Vision-and-Language Models
A method for reducing unsafe concept associations in CLIP while preserving useful vision-language behavior.
Nov 27, 2023