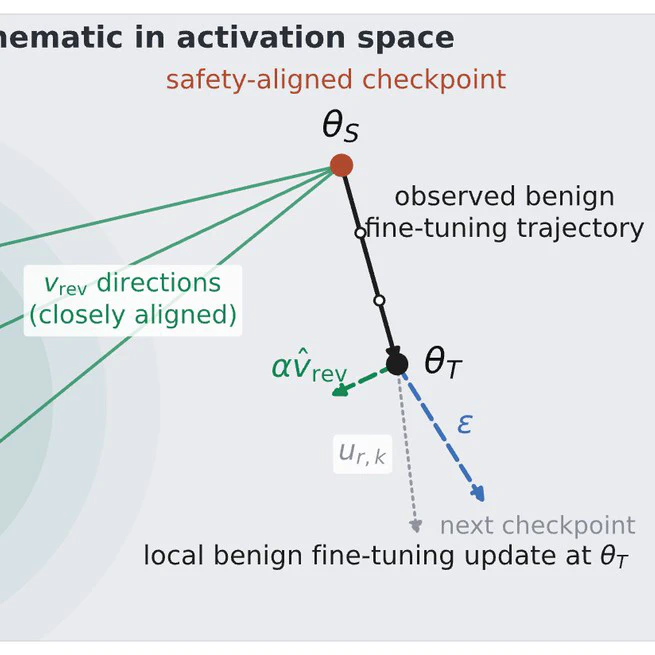
A Gravitational Interpretation of Safety Reversion under Fine-Tuning
Benign post-training pulls safety-aligned LLMs back along a reversion direction toward an earlier, more permissive state; opposing that direction reduces harmfulness across Llama, Qwen, and Gemma.
Jun 26, 2026

Not All Attackers Are Malicious: When Safety Degrades Without Harmful Intent
A talk on how safety can silently degrade when models are adapted after deployment, even without malicious intent.
Feb 9, 2026